38 posts
- § 38Update·1 min read
Qronos joins the Lumen partners
Qronos AI runs its LLM gateway on Lumen and hosts a Discord community for AI roleplay and storytelling. Who they are, and how our partner program works.
announcementcommunityRead more - § 37Update·3 min read
Consent per provider, for free and paid models
Consent on Lumen now belongs to the provider instead of the free model, and one consent covers every model that provider serves, paid or free. Here is who asks, how to consent or object, and what API clients will see.
announcementprivacyRead more - § 36Update·2 min read
Free models now ask for your consent
Free models are served by providers that may use your inputs for their own purposes. You now confirm that once per model. Here is why and how.
announcementprivacyRead more - § 35Update·2 min read
Where your requests go: provider labels, image marking and privacy updates
Every model page now shows where each provider is based and flags countries without EU data protection safeguards. Here is what the labels mean, how to choose your route, and what else changed.
announcementprivacyRead more - § 34Update·2 min read
What happened with LoreBary, and what Lumen stores about you
For four days we served LoreBary's in-house model without permission. Here is what happened, what we changed, and exactly what Lumen keeps about you.
announcementcommunityRead more - § 33Engineering·4 min read
The Claude fake detector is now an open-source library
ai-model-verifier is the engine behind our model tester, published on npm under AGPL-3.0. Give it a base URL, a key and a model and it tells you whether the endpoint serves what it sells, now with thinking-signature and token-billing checks.
engineeringannouncementRead more - § 32Product·2 min read
The server tag now cuts your free model wait
Wearing the Lumen Discord tag shortens your free-model rate limit window by 25 percent, so a model you could call once a minute you can call every 45 seconds.
productRead more - § 31Product·1 min read
How to connect Lumen to Nevika
Nevika takes any OpenAI-compatible endpoint as a custom proxy. Here is the one minute setup, which model to pick, and the two errors people hit.
productRead more - § 30Product·3 min read
Claude Opus 4.8 vs 4.6 vs 4.7 for roleplay: a hands-on ranking
A roleplayer ranks three Claude Opus versions on Lumen: memory, emotional depth, drive, and creative writing. 4.8 wins, 4.6 beats 4.7, and each one wins or slips in a clear place.
comparisonproductRead more - § 29Product·1 min read
Lumen vs SpicyChat: the easy path, plus depth, models, and code
SpicyChat is a zero-setup RP site whose memory and context are gated behind paid tiers. Lumen keeps the easy start but adds 200+ models you choose, deep lorebooks, and a key that also runs coding agents.
comparisonproductRead more - § 28Product·1 min read
Lumen vs Agnai: the same RP depth, hosted, on one key
Agnai is an open-source RP frontend whose standout is true multiplayer: several humans and several bots in one chat. Lumen has single-user RP depth hosted, where the key is the account and also runs coding agents.
comparisonproductRead more - § 27Product·1 min read
Lumen vs Open WebUI: 200+ hosted models, no Ollama, plus character chat
Open WebUI is a self-hosted, Ollama-first chat UI you run and key up. Lumen is 200+ hosted models on one key, no infra, plus a real character client, and the key codes too.
comparisonproductRead more - § 26Product·1 min read
Lumen vs LibreChat: multi-model chat, hosted, plus character chat
LibreChat is a self-hosted, MIT, BYOK ChatGPT clone. Lumen is hosted multi-model chat where the key is the account, plus a real character client, on one key that also codes.
comparisonproductRead more - § 25Product·1 min read
Lumen vs Lumiverse: the memory ideas, hosted, plus code
Lumiverse is a source-available role-play suite whose Memory Cortex (entity graph, tiered consolidations, cross-chat vaults) is the deepest RP memory around. Lumen carries the same ideas in a hosted 2-in-1 where one key also runs coding agents, and is free to use commercially.
comparisonproductRead more - § 24Product·1 min read
Lumen vs Marinara: we ported the preset engine into a 2-in-1
Marinara Engine is a standalone, self-hosted role-play, visual-novel, and game app built around 22 built-in agents. Lumen carries the same agent-pipeline idea in a hosted product where one key also runs coding agents.
comparisonproductRead more - § 23Product·1 min read
Lumen vs Chub / Venus: the card depth, plus code on one key
Chub (Venus) is a card library and chat with tiered models or BYOK. Lumen has the cards and lorebook depth plus 200+ models on one key that also runs coding agents.
comparisonproductRead more - § 22Product·1 min read
Lumen vs SillyTavern: same depth, hosted, on one key
SillyTavern is the power-user character front-end you self-host and feed your own keys. Lumen has the same depth hosted, where the key is the account and also runs coding agents.
comparisonproductRead more - § 21Product·1 min read
Lumen: the open source OpenRouter alternative
OpenRouter is closed source. Lumen does the same one key, 200+ model job with the entire stack public under OSI licenses, self hostable, and with a hosted free tier to test on.
comparisonproductRead more - § 20Product·1 min read
Lumen vs Character.AI: open models and a real key
Character.AI is a closed, filtered chat with no API and no model choice. Lumen is open: 200+ models, a real OpenAI-compatible key, your data local, and the same key codes too.
comparisonproductRead more - § 19Product·1 min read
Lumen vs Janitor.AI: the backend, plus a chat of your own
Janitor.AI is a character chat front-end that needs a backend. Lumen is that backend on one key, and it has its own character chat too, so you can stay in one place.
comparisonproductRead more - § 18Product·3 min read
One API key for Claude Code and character chat
Coding agents and character chat clients both speak OpenAI-compatible APIs. Here is how one key powers Claude Code and your character chats from a single balance.
productRead more - § 17Product·3 min read
How to connect any LLM to SillyTavern
SillyTavern can talk to almost any model through one OpenAI-compatible endpoint. Here is the exact setup, how to switch models, and how to fix common errors.
productRead more - § 16Engineering·3 min read
What is an LLM gateway?
An LLM gateway is one endpoint and key that routes requests to many model providers. Here is what it does, why it helps, and who actually needs one.
productRead more - § 15Product·2 min read
The best OpenRouter alternatives in 2026
OpenRouter is not the only way to reach many models from one key. Here are the alternatives worth knowing in 2026, what each is good for, and how to pick.
comparisonproductRead more - § 14Product·3 min read
The best AI gateway for SillyTavern in 2026
SillyTavern needs an OpenAI-compatible endpoint and a key. Here is what actually matters when you pick a gateway, and how to connect one in under a minute.
comparisonproductRead more - § 13Product·2 min read
Lumen vs nano-gpt: chat marketplace or one key for both
nano-gpt offers a huge model catalog behind a chat UI. Lumen gives you the same pay-as-you-go access plus a real developer API and a built-in character client, under one clean key.
comparisonproductRead more - § 12Product·2 min read
Lumen vs Portkey: AI gateway or full LLMOps platform
Portkey is an enterprise LLMOps platform with observability, guardrails, and governance. Lumen is a simpler hosted gateway with a built-in chat client. The choice is how much platform you actually need.
comparisonproductRead more - § 11Product·1 min read
Lumen vs MegaLLM: same coder gateway, plus a chat client
MegaLLM is a popular frontier-model gateway for coding agents. Lumen does the same job and adds a built-in chat and character client. The difference is whether you only ship code or also want a place to chat.
comparisonproductRead more - § 10Product·2 min read
Lumen vs RisuAI: we ported the character chat engine into a hosted 2-in-1
RisuAI is the power-user character chat frontend. Lumen ported its engine (lorebooks, CBS macros, triggers, regex, card import) into a hosted product where the same key also drives coding agents. Not a rival, a 2-in-1.
comparisonproductRead more - § 09Product·1 min read
Lumen vs LiteLLM: hosted gateway or self-hosted proxy
LiteLLM is the most popular self-hosted LLM proxy. Lumen is a hosted gateway with a built-in chat client. The real choice is whether you want to run the infrastructure yourself.
comparisonproductRead more - § 08Product·3 min read
We aggregated 130+ free AI models from about 50 providers into one endpoint
We wired about 50 free providers into Lumen: 130+ free models, one OpenAI-compatible endpoint, $0 per token. They carry upstream limits we cannot raise, plus a light 1-per-minute cap we add to keep the shared pools fair. Here is the honest version.
announcementproductRead more - § 07Product·2 min read
Where to find Lumen: our directory listings
Lumen is listed across the AI tool and startup directories. Here is where you can find us, verify the listings, and read independent takes.
announcementproductRead more - § 06Product·1 min read
Lumen vs OpenRouter: an honest comparison
Lumen and OpenRouter both put many models behind one OpenAI-compatible key. The difference is what sits on top: a headless API, or an API plus a built-in chat and character client. Here is the honest version.
comparisonproductRead more - § 05Update·2 min read
Join the Lumen Discord, get free balance
Link your account for $1, boost the server for $1 every month, hunt bugs for up to $50. We just opened the Lumen Discord.
announcementcommunityRead more - § 04Engineering·3 min read
Which image models actually take 6 reference inputs? We ran the benchmark.
Many image models advertise multi-reference editing, but availability across resellers varies wildly. We sent a fixed 6-image scene-composition prompt to every image channel in our catalog. 332 channel runs, 136 unique models, 54 with at least one verified passing provider.
engineeringannouncementRead more - § 03Engineering·5 min read
How we tell real Claude from a fake
Cheap Claude is often another model wearing Claude's name. Why asking the model proves nothing, why the knowledge cutoff is a guess, and the checks that actually catch a fake.
engineeringannouncementRead more - § 02Engineering·2 min read
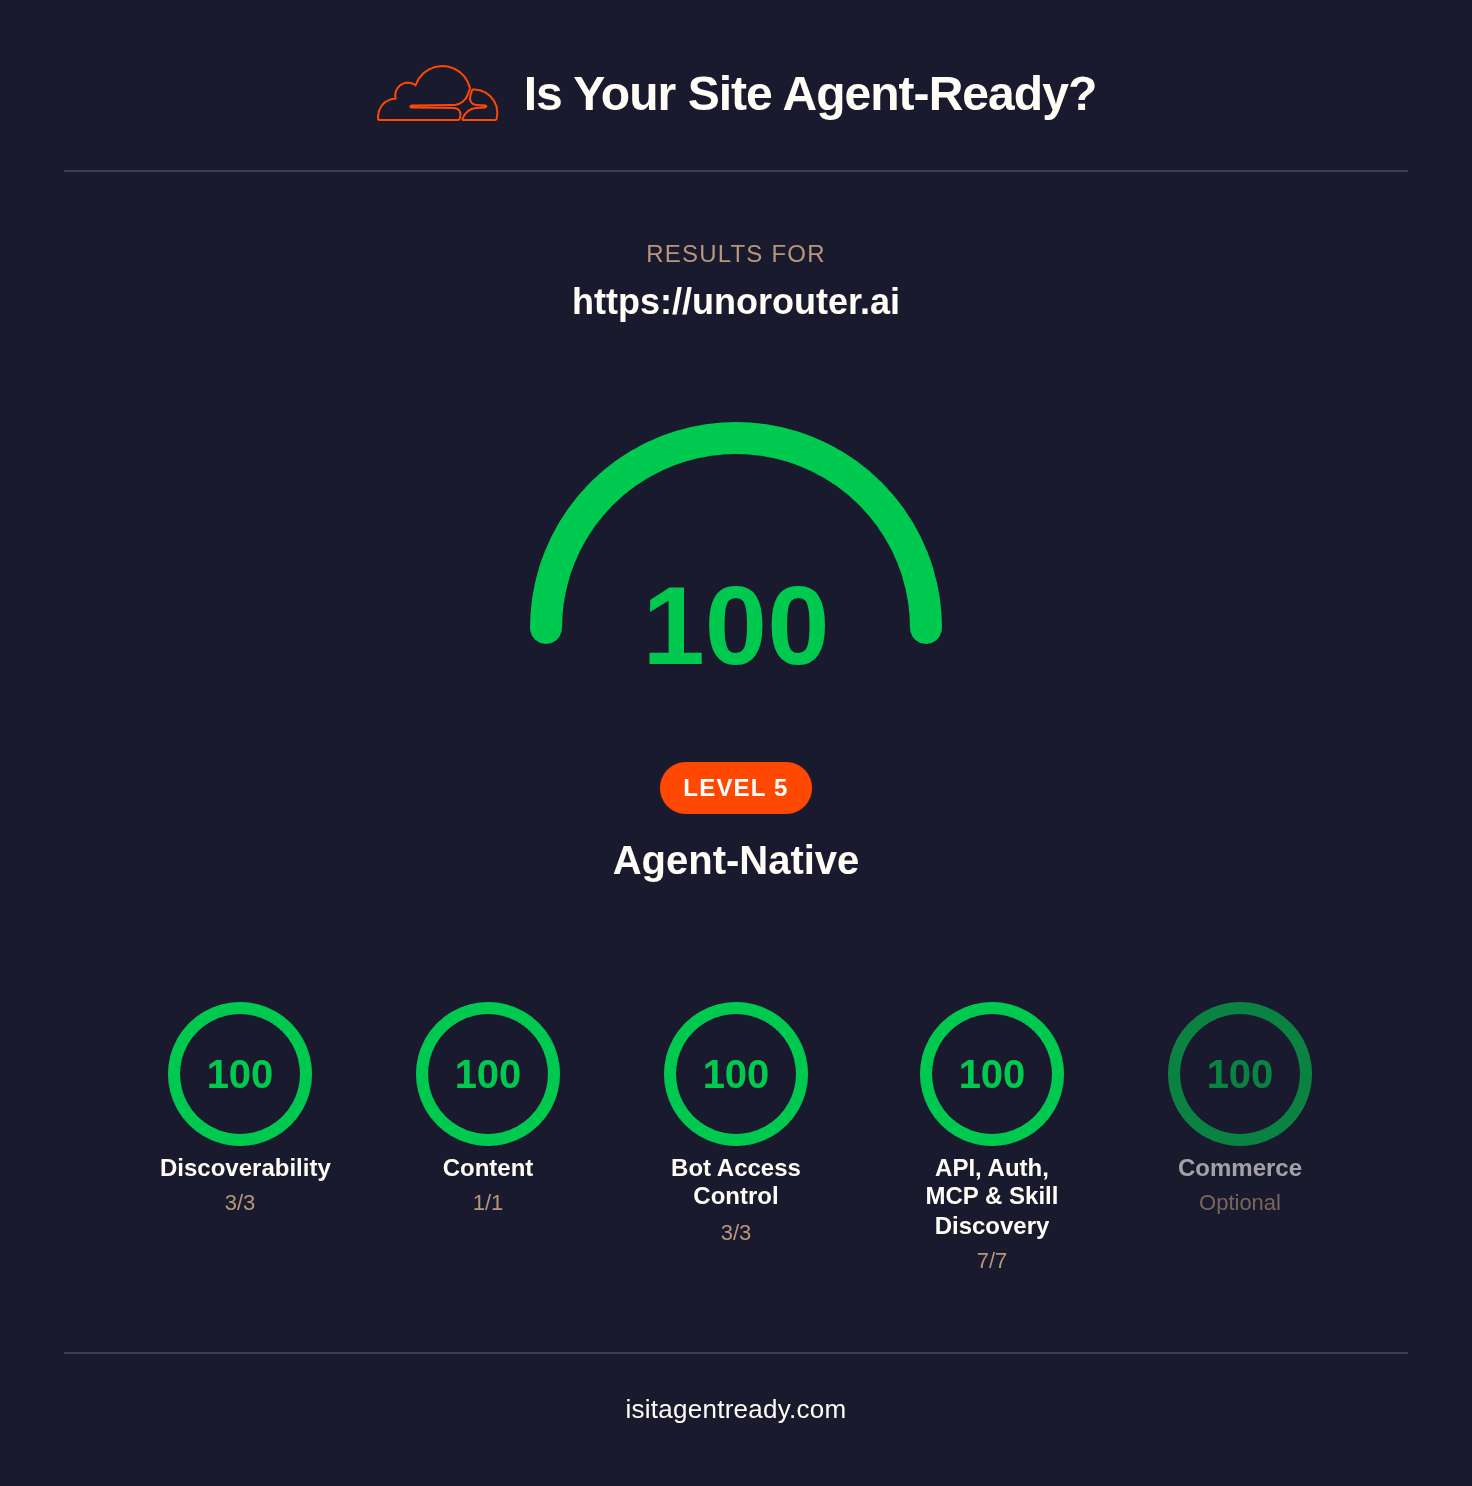
We pointed Cloudflare's agent scanner at our site. It came back 100/100.
Cloudflare just shipped a scanner that grades how ready your site is for AI agents. We hit a perfect 100/100 and the top Level 5 rating. Here is exactly what it checks and why most sites fail.
engineeringannouncementRead more - § 01Launch·1 min read
We got tired of fake Claude. So we built Lumen.
Outages every other week. Premium models silently swapped for cheap clones. We snapped, shipped our own router, and made it paranoid about both. Here is the launch story.
announcementproductRead more